
In daily maintenance work you regularly decide whether a faulty component has to be replaced immediately or whether the repair can wait until the next planned downtime. Without clear criteria, that judgement varies from shift to shift and leads to avoidable failures or unnecessary effort. This article places corrective maintenance among the available maintenance strategies and shows you when it fits and where its limits lie.
Key takeaways
Corrective maintenance only responds once a fault has been detected, which sets it apart from preventive measures.
Deferred and immediate measures require different prioritisation criteria depending on criticality and risk.
The strategy pays off mainly for non-critical, redundant or quickly replaceable equipment.
Recurring faults, rising MTTR values or safety risks are typical triggers for moving to preventive or predictive approaches.
The Vetter practical example shows how a digitally structured fault process shortens communication paths and secures experience-based knowledge.
What is corrective maintenance?
Corrective maintenance covers all maintenance measures carried out after a fault has been detected in order to restore a machine or plant to a functional condition. Practitioners also call it reactive maintenance, because the maintenance team only responds to a malfunction, a defect or a loss of function.
In everyday manufacturing, corrective maintenance mainly involves fault finding, diagnosis, repair, functional testing and documentation. A typical case is replacing a faulty sensor after a machining centre has come to an unplanned standstill.
The trigger is not always a complete machine breakdown. An error message, a quality problem or an identified functional restriction also leads to a corrective measure. Examples include a leaking pneumatic hose, a proximity sensor that switches unreliably, or a drive that no longer reaches its specified speed.
Goal: restore operating condition quickly and sustainably
The goal is to restore a safe operating condition that meets specification, quickly and sustainably. What counts is not only a short repair time, but also preventing the same fault from recurring.
The decisive distinction is between an immediate fix and a permanent solution. A temporarily fastened cable restores function in the short term. Only proper routing with strain relief and suitable protection removes the technical weak point for good.
The label reactive says nothing about how fast your team steps in. Depending on criticality and risk, the repair happens immediately or at a planned later point in time.
How do corrective, preventive and predictive maintenance differ?
Corrective maintenance responds to a fault that has occurred, preventive maintenance intervenes at fixed intervals, and predictive maintenance derives measures from condition data. None of the three strategies is economically superior for all equipment.
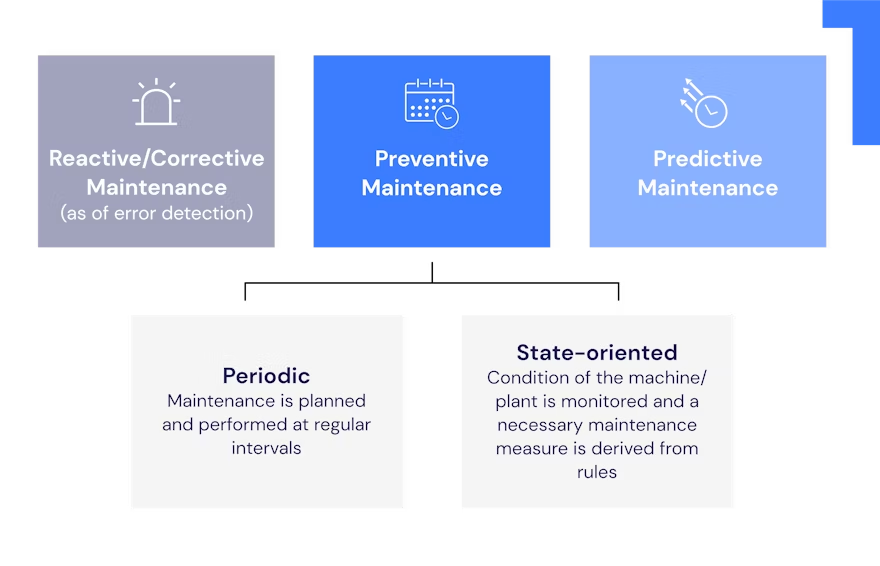
Recommendation: Assign the strategy by criticality and fault pattern. Corrective maintenance suits non-critical equipment, preventive measures suit predictable wear, and predictive approaches suit critical plants with meaningful condition data.
Difference from preventive maintenance
Preventive maintenance takes place as planned before a fault, corrective maintenance only after the fault has been detected. The key difference therefore lies in the point of intervention and in how well resources can be planned.
Preventive measures are based on operating hours, switching cycles or fixed calendar intervals, for example. This includes the scheduled replacement of a filter, the lubrication of a bearing or the exchange of a wear part after a defined running performance.
The preventive strategy is the better choice when a failure causes high safety, quality or downtime costs and when deterioration can be modelled from experience values. Corrective measures are more economical when a defect has few knock-on effects and the equipment can be replaced quickly and cheaply.
The most common mistake is blanket interval maintenance across all components. It creates unnecessary work and carries the risk of introducing new faults through assembly errors. An FMEA or a risk-based criticality analysis provides a more reliable basis.
Difference from predictive maintenance
Predictive maintenance detects progressive deterioration from condition data before the loss of function occurs. Corrective maintenance, by contrast, only begins once a fault is already present.
Suitable measurands for predictive approaches include vibration, temperature, current draw, pressure, oil condition or acoustic signals. Increasing bearing vibration indicates wear, for example, so maintenance can schedule the replacement in a suitable production window.
Predictive maintenance is particularly worthwhile for bottleneck plants, expensive assemblies and long spare part lead times. It does, however, require reliable sensors, sufficient historical data, defined limit values and qualified analysis. Without that foundation you get warning messages from which your team cannot derive reliable action.
What forms of corrective maintenance are there?
Corrective maintenance splits into deferred and immediate measures. The choice depends on the criticality of the plant and on the consequences for safety, quality, the environment, delivery capability and cost.
A sound decision requires defined priority classes and escalation rules. Without them, every shift decides differently even though the faults are comparable.
Deferred corrective maintenance
In deferred corrective maintenance the team detects and documents a fault but carries out the repair at a later point in time, in line with internal maintenance policies. The prerequisite is that continued operation remains safe and under control.
Typical examples are a defective indicator light with no effect on machine function, a damaged housing part outside the hazard zone, or a failed unit in a redundant system. The team adds the job to the backlog and schedules it for a setup process, a production-free shift or a planned shutdown.
Checks before deferring a repair
Before deferring, the responsible role, for example shift management or maintenance management, should check at least the following points:
Is there a risk to employees?
Does the fault affect product quality, inspection processes or traceability?
Is there a risk of consequential damage to assemblies or tools?
Will the plant remain stable in operation until the repair date?
Are spare parts, qualifications and time slots available for the later repair?
Is the deviation documented with an owner, a deadline and the permitted operating condition?
As soon as safety functions, product conformity or environmental protection are affected, deferral is not an option. The team must then bring the plant into a safe condition and assess it without delay.
Immediate corrective maintenance
Immediate corrective maintenance starts directly after fault detection, because the defect stops operation or creates an unacceptable risk. It takes priority for critical plants, safety issues and quality-relevant faults.
One example is the failure of a main drive in a linked production line. Shift management secures the process, maintenance locates the fault and replaces the defective component. Functional testing and a controlled release back into operation follow.
In practice a clear prioritisation works well, ranging from critical stoppages to defects that can be planned. Faults on guarding, utility supplies, bottleneck plants or processes whose interruption immediately causes scrap and late deliveries are particularly critical.
What are the benefits of corrective maintenance?
Corrective maintenance reduces preventive planning effort and uses components up to the point of fault or loss of function. These benefits come into their own mainly with non-critical, low-cost and easily replaceable equipment.
The strategy is not automatically cheap. It only becomes economical when repair costs, downtime costs and possible consequential damage stay lower than the effort for preventive or predictive measures.
Lower planning and administrative effort
A reactive approach needs neither fixed maintenance intervals nor continuous condition monitoring before the fault occurs. In the short term this reduces planning, inspection and administrative effort.
For a simple workplace light, a redundant fan or a quickly replaceable standard device, that makes sense. The operation uses the full technical service life and ties up no capacity for routine interventions.
The process also stays straightforward: report the fault, set the priority, narrow down the cause, carry out the repair and check function. That advantage disappears, however, as soon as frequent faults pull the maintenance team out of planned work or require high spare part stocks.
The repair as an inspection opportunity
A repair opens direct access to the affected assembly and therefore a targeted opportunity for inspection. So do not just replace the failed part, but also check adjacent components and possible damage mechanisms.
With a defective bearing, for example, the shaft, bearing seat, lubrication, seal, alignment and vibration behaviour all belong in the inspection. That way maintenance can tell whether overload, contamination or incorrect assembly caused the damage.
A short standardised inspection list works well in practice. It stops time pressure during a fault from pushing visible signs such as abrasion, loose connections, leaks or thermal discolouration into the background.
What are the drawbacks and risks of a purely reactive approach?
On critical plants a purely reactive strategy leads to unplanned faults, resources that are hard to plan and higher failure costs. Systematic faults also persist if the team only restores function and carries out no root cause analysis.
The strategy is particularly problematic in linked lines, continuous processes and plants with safety or quality critical functions. There, the follow-on costs of a failure quickly exceed the maintenance effort saved.
Unpredictable faults and missing early warning signals
Without inspections, condition monitoring and structured fault analysis there are no early warning signals and no reliable patterns. Maintenance only learns about the problem once a function is restricted or fails.
That makes the operation unpredictable not only technically but also organisationally. Skilled staff, tools and spare parts have to be available at short notice. At the same time, planned improvement measures and preventive work fall behind.
A pure repair often only removes the visible symptom. With recurring faults you should use 5 Why, Ishikawa or an 8D approach to reach the technical root cause. Otherwise quick troubleshooting turns into a permanent fault loop.
Production interruptions and true failure costs
The failure of a critical piece of equipment interrupts material flow and reduces availability, OEE and delivery reliability. In linked production lines a local defect often affects upstream and downstream stations too.
Beyond the actual repair time, waiting times arise for diagnosis, spare part procurement, release and restart. Employees are left without value-adding work, material piles up ahead of the fault or downstream processes run empty.
True failure costs therefore go well beyond the working time of the maintenance team. Scrap, rework, overtime, special transport and rescheduling belong in the assessment as well.
Shorter service life through missing basic care
If an operation only intervenes at the point of functional loss, wear, contamination, lubrication deficits and early loosening go undetected for a long time. Small amounts of damage then spread to neighbouring components and shorten the usable service life of the plant.
A worn bearing puts load on the shaft and housing, for example. A small leak lowers the lubricant level and later causes larger damage. Regular cleaning, inspection and lubrication as part of 5S, autonomous maintenance or TPM break such damage chains.
Corrective maintenance therefore does not replace continuous basic care. Even under a largely reactive strategy, safety-related inspections and mandatory maintenance measures have to remain in place.
When does corrective maintenance make economic sense?
Corrective maintenance makes economic sense when a failure causes low follow-on costs, creates no relevant safety or quality risk, and the repair is quick. Standardised spare parts, short procurement times and existing redundancies are good conditions.
For the decision you should look beyond the price of the faulty component. What matters are the total costs of the fault event.
Corrective maintenance fits above all when:
the equipment is not production critical,
its failure endangers nobody,
product quality and traceability remain untouched,
no significant consequential damage occurs,
a replacement device or a redundant function is available,
diagnosis and replacement take little time,
the spare part is cheap and available at short notice,
a planned preventive intervention would cost more than the expected failure.
A typical example is a single standard fan in a redundant ventilation system. A main drive without redundancy, a safety-related control system or a bottleneck machine, on the other hand, does not belong in a pure run-to-failure strategy.
When is it worth switching to preventive or predictive maintenance?
A change of strategy pays off as soon as recurring failures, high downtime costs or critical risks outweigh the effort for preventive measures. Preventive maintenance suits known wear progression, predictive maintenance suits measurable condition deterioration.
Concrete triggers for a switch are:
The same type of fault occurs repeatedly.
MTTR rises or spare parts are regularly missing.
A plant affects the bottleneck and therefore has a significant impact on OEE.
Failures cause scrap, rework or late deliveries.
The defect affects occupational safety, the environment or product conformity.
Binding requirements demand inspection or maintenance intervals.
Vibration, temperature or other condition variables provide usable warning time.
In practice a hybrid strategy works well. Critical assemblies receive preventive or predictive measures, while non-critical standard components are maintained correctively. This combination focuses budget and skilled staff on the biggest operational risks.
How can you fix unplanned machine failures quickly and sustainably?
A structured fault process combines fast restoration with safe working, clean documentation and root cause elimination. Without a standardised sequence, repair quality depends too heavily on shift, person and time pressure.
A workable sequence consists of the following steps:
Record the fault: Document the machine reference, time, error code, operating condition, product and visible symptoms.
Make the plant safe: Assess hazards, control energy sources and follow the rules for safe isolation.
Set the priority: Assess the impact on safety, quality, the environment, the bottleneck and delivery capability.
Diagnose the fault: Check symptoms, review the fault history and systematically narrow down the affected assembly.
Restore function: Repair or replace defective components and clearly mark any temporary measures.
Verify effectiveness: Test the plant under defined conditions, check quality characteristics and document the release.
Assess the cause: Use 5 Why, Ishikawa or 8D for critical or recurring faults.
Capture the findings: Document cause, solution, spare parts, images and test results so other shifts can reuse them.
Recommendation: Separate restart from sustainable closure explicitly in your fault process. Manufacturing may continue after a safe immediate measure, but the case stays open until the cause is removed and effectiveness is verified.
Reducing unpredictability without a full prevention strategy
Just a few targeted measures reduce the uncertainty of a largely reactive strategy. A criticality assessment, digital fault reports, defined spare part stocks and simple inspection routines are particularly effective.
A hybrid approach does not require sensors everywhere. Start with bottleneck plants and recurring faults. There, operating hour counters, temperature limits, visual checks or simple vibration measurements often provide enough information for earlier intervention.
Poka Yoke and 5S contribute as well. Unambiguous connections prevent assembly errors, marked target states make deviations visible, and orderly workplaces shorten the search for tools and spare parts.
Identifying and analysing the causes of recurring faults
Structured fault data turns individual repairs into a usable fault picture. To achieve that, teams have to record fault type, cause, measure, downtime and affected component consistently.
Free text alone makes analysis difficult. Standardised categories for mechanical, electrical, pneumatic, hydraulic, software-related and operator-related causes are the better choice. Images, videos, error codes and comments add the necessary context to those categories.
A Pareto analysis shows which fault types account for the largest share of downtime or repair effort. Root cause analysis and continuous improvement measures follow for those focus areas. Corrective maintenance then develops step by step from a repair function into a learning organisation.
Practical example: how Vetter supports corrective maintenance digitally
In the Vetter practical example, Operations1 supports a centrally documented fault process. In shift operation this creates a shared level of information and makes collaboration in the maintenance team easier.
Vetter manufactures fork tines for forklift trucks. The maintenance team keeps the production plants available across several manufacturing areas and handles acute faults during the day.
Limits of the previous custom software
According to the underlying practical report, the custom-developed maintenance software no longer covered new requirements sufficiently over time. Vetter therefore decided in favour of cloud-based standard software.
Custom software often fits the existing process precisely at first. Without continuous maintenance, however, technical and functional gaps appear. Changes take longer, knowledge about the application concentrates on a few people, and new proven practices do not flow in automatically.
In the practical example, the project team mapped the specific use case in the new platform together. What mattered was not only the technical rollout, but also a clear model of roles, reporting paths and processing status.
The digital fault reporting process step by step
The digital process bundles machine reference, documentation and processing status into one traceable case. Operations1 links tasks to the associated report and provides a searchable and filterable task overview.
The sequence described at Vetter follows a clear order:
An employee records the fault with a machine reference in a report.
The team creates a task from the report for further processing.
Photos, videos or PDF files add detail to the fault description.
The team assigns the task to a responsible person or user group and sets a due date.
The responsible person works on the fault and updates the status of the task.
Once completed, the task remains referenced in the associated report and can be found for later analysis.
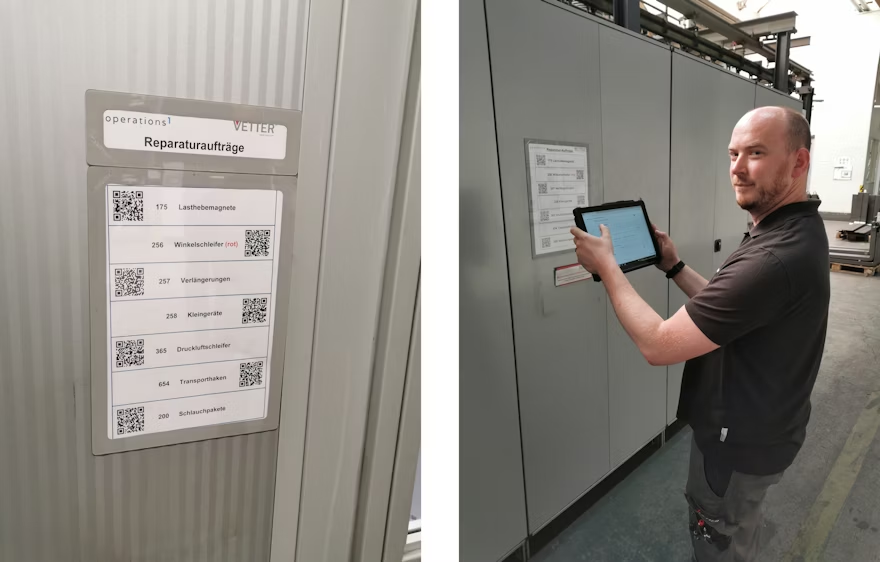
This sequence reduces media breaks between paper reports, phone calls and spreadsheets. At the same time it creates a traceable history for later analysis of comparable faults.
Effects for the maintenance team
The maintenance team can record unforeseen incidents centrally and track their processing status transparently. The shared data basis improves knowledge sharing and traceability across shifts and manufacturing areas.
Images and videos reduce follow-up questions, because the responsible specialist can assess the fault before arriving at the machine. Responsibilities and status information show shift management whether an incident is open, in progress or closed.
The lasting value comes from the documented fault history. Recurring faults become visible, solutions are ready for later use, and maintenance management gains a basis for preventive measures. Digitalisation does not replace technical expertise. It makes existing knowledge available faster so that it is not lost at the shift handover.
Conclusion: use corrective maintenance deliberately and complement it
Corrective maintenance is the right strategy for non-critical equipment with low failure consequences and simple repairs. For bottleneck plants, safety functions and quality critical processes, a purely reactive approach is not enough.
The most economical route is a risk-based combination. You handle non-critical faults correctively, plan known wear measures preventively, and monitor critical assemblies predictively with suitable condition data.
The Vetter practical example also shows how a digital fault process gives structure to reactive maintenance. Clear responsibilities, media-rich documentation and a central fault history shorten communication paths and secure experience-based knowledge. Use that data afterwards for Pareto analyses, 5 Why, Ishikawa and continuous improvement, and individual repairs turn into targeted measures against recurring failures.
FAQ
Why is it also called reactive maintenance?
The term reactive maintenance describes the timing of the strategy: only a detected fault triggers the measure. Unlike preventive or predictive strategies, no targeted intervention takes place before the fault. Both terms describe the same approach and are used interchangeably in day-to-day operations.
What is the difference between servicing and corrective maintenance?
Corrective maintenance is not the same as servicing. Servicing preserves the functional condition of a plant. Corrective maintenance restores that condition after a fault and therefore consists mainly of repair work.
Which KPIs are relevant for corrective maintenance?
Mean time to repair, or MTTR, is a central KPI for operational management. It describes the average time from the start of the repair to the restoration of function. In addition, operations should evaluate response time, technical downtime, repeat fault rate and the impact on OEE.